EnterpriseRAGAISystems&VectorKnowledgeBases
Engineering secure Retrieval-Augmented Generation (RAG) architectures and vector search pipelines that ground Large Language Models directly in your proprietary enterprise data—delivering verifiable, zero-hallucination intelligence.
AI & Agentic Solutions 🔥
8 ServicesRequest a Proposal
Eliminate Hallucinations and Turn Proprietary Company Data into Actionable Intelligence
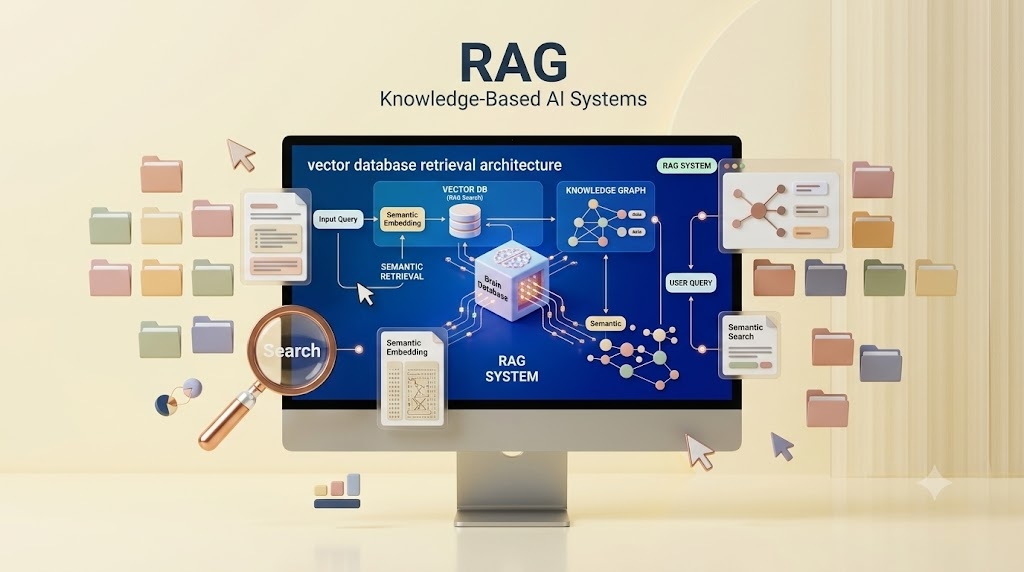
Standard Large Language Models generate persuasive answers, but their generic public training data makes them unreliable for enterprise use cases where precision, citations, and strict factual correctness are critical. Retraining or fine-tuning models continuously is cost-prohibitive and fails to reflect real-time operational updates. At Bhavya Web Tech, we engineer custom Retrieval-Augmented Generation (RAG) platforms that dynamically fetch verified context from your private company knowledge bases before generating any response.
Our RAG architectures combine advanced semantic vector indexing, hybrid keyword-vector retrieval, and automated document ingestion pipelines. By querying internal knowledge repositories—including PDF manuals, technical documentation, SQL databases, customer support tickets, and ERP records—our systems ground every AI generation in source truth. With strict tenant isolation, role-based access control (RBAC), and visible source citations, we deliver secure, compliant internal and customer-facing intelligence engines.
Core Features
Hybrid Vector & Keyword Search (BM25 + Dense Embeddings)
Combines semantic context matching with exact lexical keyword search to deliver unmatched retrieval precision.
Dynamic Document Ingestion Pipelines
Automated parsing, chunking, and embedding of unstructured PDFs, spreadsheets, Word docs, Notion workspaces, and Confluence wikis.
Enterprise Vector Database Integration
Scalable vector index setups utilizing Pinecone, pgvector (PostgreSQL), Qdrant, Milvus, or Weaviate for sub-second query retrieval.
Verifiable Citations & Source Attribution
Every generated response includes direct clickable citations and excerpt highlights back to the exact source document and page.
Role-Based Access Control (RBAC) & Data Isolation
Document-level and tenant-level security permissions ensuring users and agents only retrieve data they are authorized to view.
Re-Ranking & Context Window Optimization
Cross-encoder re-ranking layers (Cohere Rerank, BGE) that filter out noise and compress context before sending prompts to the LLM.
Why Partner With Us?
Our Strategic Workflow
We utilize a highly refined, transparent, and step-by-step methodology designed to ensure absolute precision and flawless delivery of your enterprise project.
Step 01: Knowledge Audit, Chunking & Embedding Strategy
We review your proprietary document formats, structure metadata schemas, select optimal embedding models, and design semantic chunking strategies to minimize data loss.
Step 02: Vector Pipeline & Re-Ranking Engineering
Our developers set up the vector database, implement automated ETL ingestion pipelines, configure hybrid search algorithms, and code cross-encoder re-ranking layers.
Step 03: Retrieval Benchmark QA, Security Audits & Deployment
We evaluate retrieval recall and precision against ground-truth benchmark questions, enforce RBAC permission boundaries, and deploy the RAG system to private cloud infrastructure.
Frequently Asked Questions
Ready to build high-performance Enterprise RAG AI Systems & Vector Knowledge Bases?
Tell us about your project goals, timelines, and requirements. Our design & engineering team will deliver a structured roadmap within 24 hours.